Writing
Verified, Not Trusted: Designing Evals for AI Applications
Evals measure AI application behavior at the system boundary using deterministic graders and explicit rubrics. Results identify the model, effort and pass rates.
Topic
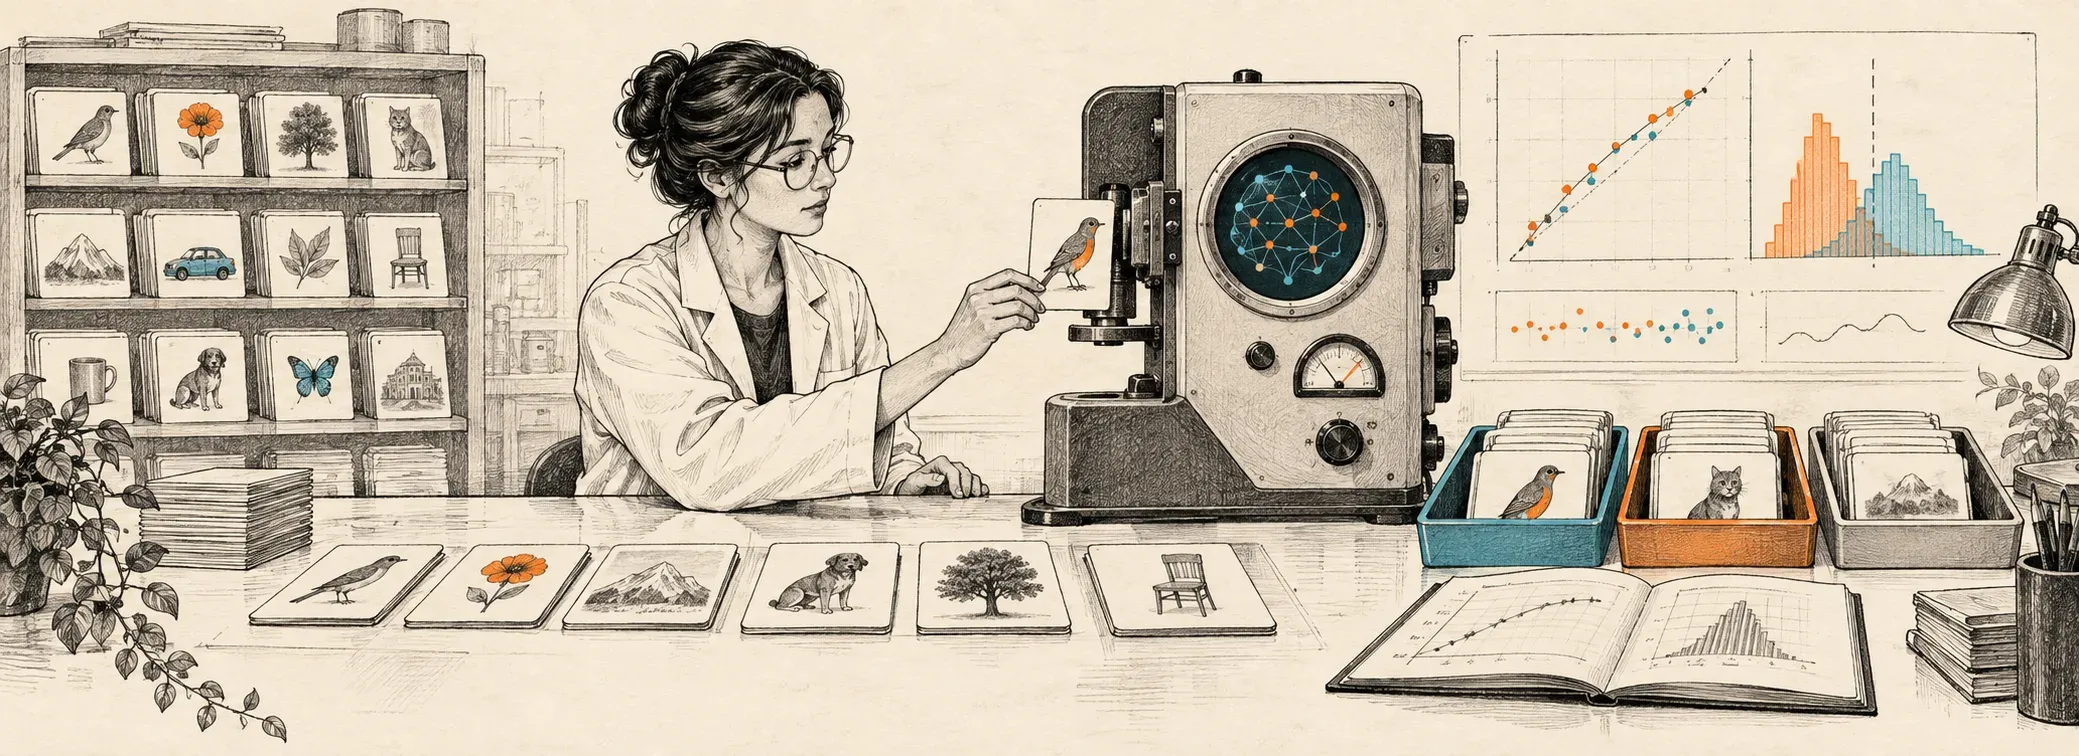
Measuring model decisions on representative labeled cases, including error costs, calibration, thresholds, abstention, and performance after changes.
4 pages
Writing
Evals measure AI application behavior at the system boundary using deterministic graders and explicit rubrics. Results identify the model, effort and pass rates.
Writing
Evals measure reliability with reference keys, code graders, model judges and pass-rate gates. Expense examples show what to check and how structured output expands coverage.
Writing
Evals are acceptance tests for prompts and skills: repeated isolated runs, a pass rate for each check, and a minimum pass rate as the gate. Code grades extracted facts and traces failures.
Writing
Jev makes bounded semantic judgments with Choice, Score, and Noul; code handles exact work and policy, while evaluation and confidence gates determine when to act or escalate.