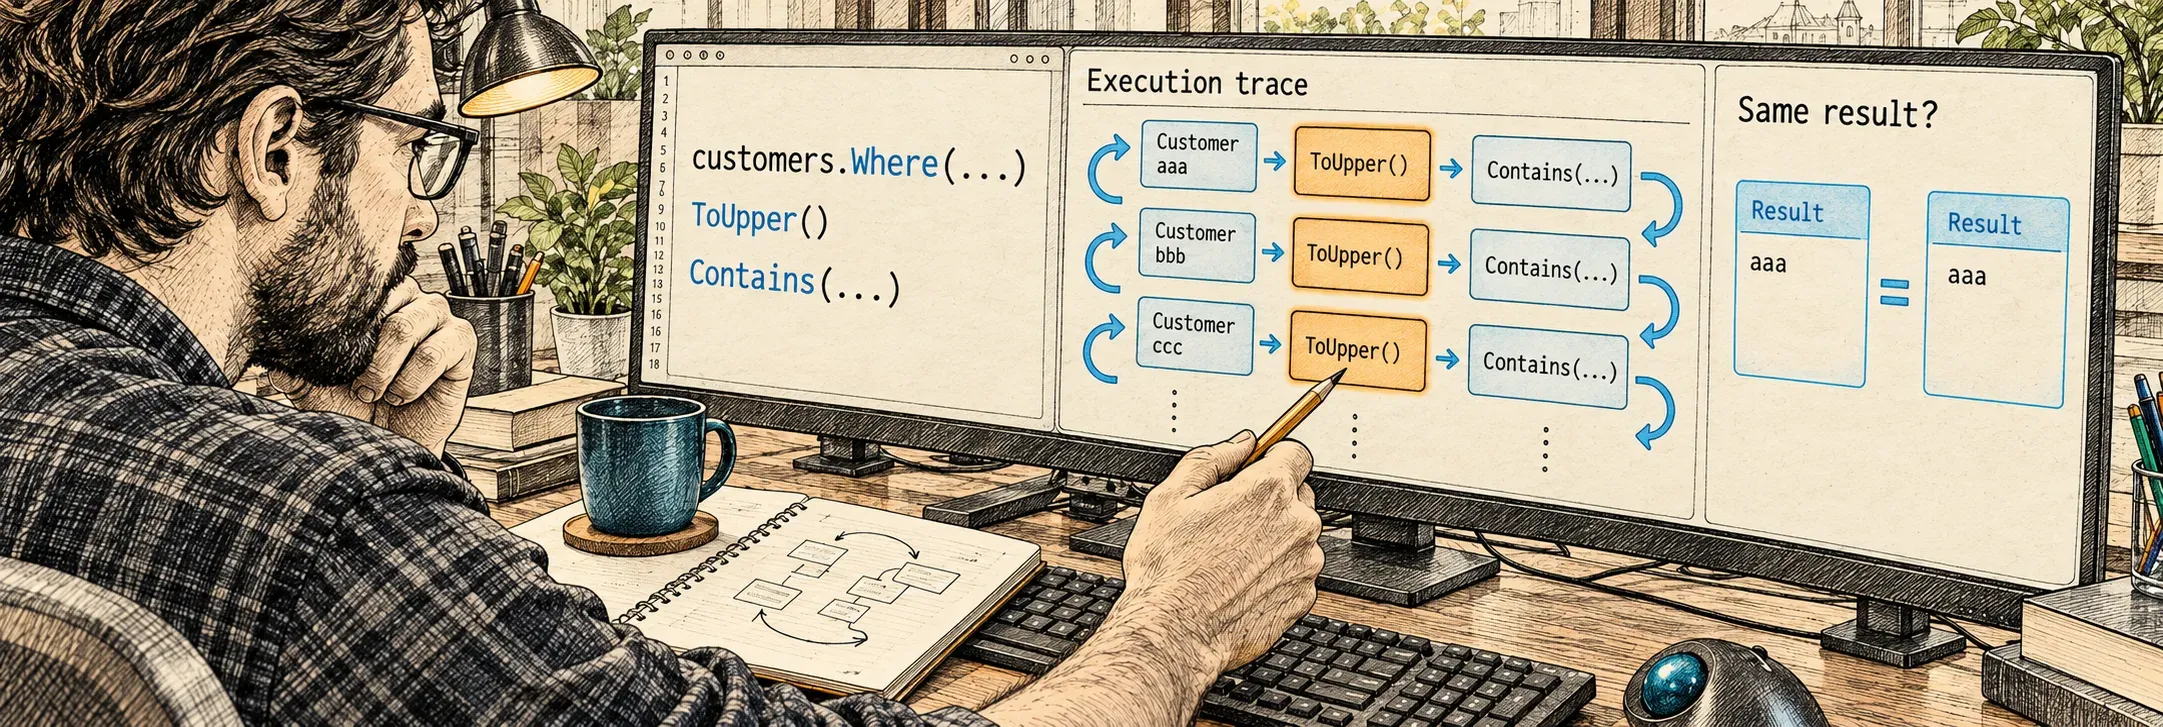
I love the concept of LINQ. I like what it lets us express in C#, and I like how little code it can take to describe a useful operation. The difficulty is that the same concise syntax can hide a surprising amount of work.
My recommendation is to use LINQ wisely. Understand what your expression asks the compiler and library to do. Keep ordinary business queries simple. In performance-critical code, start with the simplest loop that does the job and measure alternatives against it.
Let’s work through an example that began in a code review. We need to select customers whose first names occur in any of three sets. Several apparently sensible improvements made the original implementation slower in the initial experiments. Following those attempts is more instructive than being handed the final version, because it forces us to ask why an attractive change did not help.
Start with the data and the required result
We have a customer with a first name and a last name, three sets of uppercase names, and three customers whose first names are lowercase. Only the customer named aaa should match.
Here is a complete console version of the original filtering example. The benchmark attributes have been removed so it can run without a benchmarking package. Setup is moved into a constructor, and a small entry point prints the result.
using System;
using System.Collections.Generic;
using System.Linq;

internal static class Program
{
    public static void Main()
    {
        var sample = new CustomerFilter();
        foreach (var customer in sample.GetUsingMultipleToUpper())
        {
            Console.WriteLine(customer.FirstName + " " + customer.LastName);
        }
    }
}

internal sealed class CustomerFilter
{
    private readonly HashSet<string> _verifiedCustomerNames;
    private readonly HashSet<string> _certifiedCustomerNames;
    private readonly HashSet<string> _aListCustomerNames;
    private readonly Customer[] _customers;
    private readonly IEnumerable<Customer> _customersEnumerable;
    private readonly StringCaseInsensitiveComparer _stringCaseInsensitiveComparer =
        new StringCaseInsensitiveComparer();

    public CustomerFilter()
    {
        _verifiedCustomerNames = new HashSet<string> { "AAA", "DDD", "EEE" };
        _certifiedCustomerNames = new HashSet<string> { "FFF", "GGG", "HHH" };
        _aListCustomerNames = new HashSet<string> { "III", "JJJ", "KKK" };

        _customers = new[]
        {
            new Customer("aaa", "Laaaa"),
            new Customer("bbb", "Lbbbb"),
            new Customer("ccc", "Lcccc")
        };

        _customersEnumerable = new List<Customer>(_customers);
    }

    public List<Customer> GetUsingMultipleToUpper()
    {
        return _customers.Where(c =>
            _verifiedCustomerNames.Contains(c.FirstName.ToUpper())
            || _certifiedCustomerNames.Contains(c.FirstName.ToUpper())
            || _aListCustomerNames.Contains(c.FirstName.ToUpper())).ToList();
    }
}

internal sealed class Customer
{
    public string FirstName { get; }
    public string LastName { get; }

    public Customer(string firstName, string lastName)
    {
        FirstName = firstName;
        LastName = lastName;
    }
}

internal sealed class StringCaseInsensitiveComparer : IEqualityComparer<string>
{
    private readonly StringComparer _stringComparer =
        StringComparer.OrdinalIgnoreCase;

    public bool Equals(string x, string y)
    {
        return _stringComparer.Compare(x, y) == 0;
    }

    public int GetHashCode(string obj)
    {
        var hashCode = 1938039292;
        return hashCode * -1521134295
            + EqualityComparer<string>.Default.GetHashCode(obj);
    }
}
The output is:
aaa LaaaaBefore reading further, examine the predicate. What work would you remove first?
The repeated ToUpper calls stand out. A customer’s first name does not change between the three membership tests, yet we may uppercase it more than once. For these lowercase inputs, that also means allocating strings for the uppercase results.
There is one detail to keep straight: || short-circuits. Once a membership test succeeds, the remaining tests are skipped. The first customer needs one casing call, and each of the two nonmatching customers needs three. That gives seven calls for three customers, rather than an unconditional three calls per customer.
I would also question the ToList. Does the caller need a materialized list? Is it going to modify the result, or merely iterate over it? For this experiment, returning a list is part of the requirement, so every alternative must preserve that work. Removing it would change what we were measuring.
Surely a let clause will help?
We can calculate the uppercase name once and reuse it. Query syntax gives us let for precisely that sort of expression. Add this method to CustomerFilter and change the call in Main to try it:
public List<Customer> GetUsingQueryExpLetAndOneToUpper()
{
    return
        (from customer in _customers
         let firstNameUppered = customer.FirstName.ToUpper()
         where _verifiedCustomerNames.Contains(firstNameUppered)
            || _certifiedCustomerNames.Contains(firstNameUppered)
            || _aListCustomerNames.Contains(firstNameUppered)
         select customer).ToList();
}
This performs three casing calls for our three customers. We have removed repeated work, and the result remains the same. My expectation was that this would be faster.
The initial measurements went the other way. The original method averaged 527.6 ns, while the query with let averaged 655.4 ns. Those are historical measurements for this small experiment, not predictions for your runtime or application.
Why did an expression with fewer casing calls take longer? We need to inspect the implementation hidden by the query syntax.
What the compiler has to carry forward
The query must keep both the original customer and the calculated uppercase name available to later clauses. A useful way to understand its translation is this method-syntax equivalent, which can also be added to CustomerFilter:
public List<Customer> GetUsingExplicitProjection()
{
    return _customers
        .Select(customer => new
        {
            customer,
            firstNameUppered = customer.FirstName.ToUpper()
        })
        .Where(item =>
            _verifiedCustomerNames.Contains(item.firstNameUppered)
            || _certifiedCustomerNames.Contains(item.firstNameUppered)
            || _aListCustomerNames.Contains(item.firstNameUppered))
        .Select(item => item.customer)
        .ToList();
}
This explanatory version exposes the projection that carries the two values, the filter over those projected objects, and the final projection back to customers. The query-expression translation rules describe how query clauses become method calls.
We now have more than a predicate over each customer. We have introduced an anonymous object to carry values between stages and delegates for the projections. Reducing casing work was useful, but we added other work along the way.
When investigating this, look at intermediate language or decompiled C# with those transformations exposed. A decompiler configured to produce recent C# may reconstruct the same friendly query syntax you started with. Selecting an older C# output version can make generated methods, delegate construction and anonymous types easier to see.
Look for the calls and allocations that explain the measurement. Counting lines of IL does not establish performance. Nor does a newobj instruction by itself tell you how frequently that construction executes; delegate caching and runtime optimization also matter. The useful question is what extra work happens while this particular query is executed.
Three more attempts
I put the problem to colleagues, and we tried other ways to express the same selection. The following methods also belong inside CustomerFilter.
The first attempt avoids explicit casing by supplying a case-insensitive comparer:
public List<Customer> GetUsingMultipleEqualityComparer()
{
    return _customers.Where(c =>
        _verifiedCustomerNames.Contains(
            c.FirstName, _stringCaseInsensitiveComparer)
        || _certifiedCustomerNames.Contains(
            c.FirstName, _stringCaseInsensitiveComparer)
        || _aListCustomerNames.Contains(
            c.FirstName, _stringCaseInsensitiveComparer)).ToList();
}
That looks promising. We reuse the comparer, and there are no uppercase strings to create. But which Contains are we calling?
HashSet<string>.Contains takes the item to find. It does not take a separate comparer for each lookup. Adding that argument selects the LINQ extension Enumerable.Contains, which compares elements using the supplied comparer. We have changed the lookup operation as well as the casing strategy. Supplying a comparer at this call site does not reconfigure the hash set’s own lookup policy.
The sample’s custom comparer deserves attention too. Its Equals uses an ordinal case-insensitive comparison, but its GetHashCode uses the default case-sensitive string hash. That does not satisfy the requirement that equal values have equal hashes. This particular Enumerable.Contains overload uses equality comparisons, so that flawed hash implementation is not exercised here. Do not use the custom comparer to construct a hash-based collection.
A separate design to investigate would construct the sets with the framework’s StringComparer.OrdinalIgnoreCase and then use their one-argument instance Contains. That lets the set build its hash structure with the required, consistent comparer. It was not one of the original benchmark methods, and it should be tested separately. Also, current-culture ToUpper and ordinal case-insensitive comparison are different policies in general, even though these sample names produce the same match.
The next attempt merges the sets before testing membership:
public List<Customer> GetUsingMergeSetsAndSingleToUpper()
{
    _verifiedCustomerNames.UnionWith(_certifiedCustomerNames);
    _verifiedCustomerNames.UnionWith(_aListCustomerNames);

    return _customers.Where(c =>
        _verifiedCustomerNames.Contains(c.FirstName.ToUpper())).ToList();
}
Now the predicate performs one casing operation and one lookup per customer. But constructing that combined set is part of the method’s work. More seriously, UnionWith changes _verifiedCustomerNames. After the first call, that field contains names from all three categories. It no longer represents just the verified names.
This was an experiment, and that mutation is a reason to be careful with it. A benchmark that repeats the method observes an already merged set after its first invocation. A reusable combined lookup built during setup would be a different design with a different lifetime and cost.
Another attempt uses concatenation:
public List<Customer> GetUsingConcatAndMultipleToUpper()
{
    return _customers.Where(c => _verifiedCustomerNames
        .Concat(_certifiedCustomerNames)
        .Concat(_aListCustomerNames)
        .Contains(c.FirstName.ToUpper())).ToList();
}
Here the concatenation expression sits inside the predicate. For each customer, it creates a query over the three sets and asks whether that combined sequence contains the uppercase name. Concat does not create a new hash set. The apparent simplicity of the expression conceals repeated sequence construction and traversal.
All three attempts were slower than the original in the initial results. That was the enjoyable part of this exercise: every improvement we expected to see gave us another reason to investigate what the code actually did.
A local variable inside the predicate
We still have the original problem: repeated casing. We can address it without a query projection by putting a local variable inside the predicate itself:
public List<Customer> GetUsingLocalvariableAssignmentForToUpper()
{
    return _customers.Where(c =>
    {
        var firstNameUppered = c.FirstName.ToUpper();
        return _verifiedCustomerNames.Contains(firstNameUppered)
            || _certifiedCustomerNames.Contains(firstNameUppered)
            || _aListCustomerNames.Contains(firstNameUppered);
    }).ToList();
}
The uppercase value belongs to this invocation of the predicate. We use it for the three tests and then finish that invocation. There is no need to carry the customer and uppercase name through separate query stages.
This version averaged 374.3 ns in the historical comparison, the first of these LINQ rewrites to improve on the original. It retained the general Where(...).ToList() shape while removing the repeated casing calls.
That is a useful result. It also shows why “calculate it once” was an incomplete explanation of our earlier attempt. Where we put that calculation changed the machinery around it.
Compare with a simple loop
My instinct when investigating this kind of problem is to write the straightforward loop. It gives me an implementation whose work is easy to account for:
public List<Customer> GetWithoutLINQForLoop()
{
    var matchingCustomers = new List<Customer>();

    for (int i = 0; i < _customers.Length; i++)
    {
        var customer = _customers[i];
        var firstNameUppered = customer.FirstName.ToUpper();

        if (_verifiedCustomerNames.Contains(firstNameUppered)
            || _certifiedCustomerNames.Contains(firstNameUppered)
            || _aListCustomerNames.Contains(firstNameUppered))
        {
            matchingCustomers.Add(customer);
        }
    }

    return matchingCustomers;
}
It performs the same selection and returns the same kind of materialized result. There is no predicate delegate between the loop and the membership tests.
There are two meanings of baseline in this discussion. BenchmarkDotNet can label the original LINQ method as its baseline so that the table reports ratios against it. My engineering baseline is the simplest implementation I can write for the required behavior. Here that is the loop. Keeping those meanings separate avoids treating the original expression as the best available starting point merely because a benchmark labels it “baseline.”
If the simple implementation meets the requirement, we may already be finished. If another form improves readability, we can measure how much it costs and make a deliberate choice. Spending time making code elegant does not establish that it is efficient.
foreach depends on the type you enumerate
A comparable foreach method uses the same body:
public List<Customer> GetWithoutLINQForEach()
{
    var matchingCustomers = new List<Customer>();

    foreach (var customer in _customersEnumerable)
    {
        var firstNameUppered = customer.FirstName.ToUpper();

        if (_verifiedCustomerNames.Contains(firstNameUppered)
            || _certifiedCustomerNames.Contains(firstNameUppered)
            || _aListCustomerNames.Contains(firstNameUppered))
        {
            matchingCustomers.Add(customer);
        }
    }

    return matchingCustomers;
}
Notice the field being enumerated. _customersEnumerable is declared as IEnumerable<Customer> and holds a list in this setup. _customers is declared as Customer[].
An earlier comparison used foreach directly over the array. I expected the explicitly indexed loop to win, and the result did not fit that expectation. Inspecting the generated code explained why: C# has a special lowering for arrays. A foreach over a one-dimensional array can become an indexed loop, without the ordinary enumerator calls.
Using the IEnumerable<Customer> field changes the code the compiler emits. It obtains an enumerator, advances it and disposes it. The foreach specification explains the enumeration pattern and array treatment.
An array and an IEnumerable<Customer> can even refer to the same array object while producing different compiler output at their respective loop sites. The static type of the expression matters. The saved example above uses a list behind its enumerable field, so that comparison also changes the underlying collection.
Do not turn this into an unconditional rule that for is faster than foreach. Examine the actual collection type, the generated loop and the runtime you will deploy. A decompiler may reconstruct a foreach even when the IL uses indexing, which is another reason to inspect the lower-level code when the result surprises you.
Preserve what the measurements actually say
These are the means displayed in the original comparison. They document the progression that prompted the investigation:
| Implementation | Historical mean |
|---|---|
Repeated ToUpper in Where |
527.6 ns |
Contains with an external comparer |
985.2 ns |
Mutating UnionWith, then one lookup |
1,884.4 ns |
Concat inside the predicate |
1,909.3 ns |
Query expression with let |
655.4 ns |
| Local variable inside the predicate | 374.3 ns |
Loop with ToUpper |
259.1 ns |
Loop without ToUpper |
190.7 ns |
The original table’s ratio and rank entries for the merged-set case do not agree with its displayed mean, so they are not reproduced here. These values preserve the historical record; no new timing run is claimed. They also must not be combined with later loop experiments performed under different conditions or on different machines.
The last row needs particular care. Removing ToUpper makes the lowercase input names fail against the uppercase sets. That variant returns an empty list, while the required selection returns one customer. It therefore changes both casing work and result construction. Subtracting its time from the preceding row does not isolate the cost of casing alone.
To try that diagnostic yourself, copy either loop method, give it a distinct name, and use customer.FirstName directly in the membership tests. Observe the changed output before drawing conclusions from its timing. A faster implementation that returns different results is not an optimization of the required operation.
How I would investigate a change
Start by checking that the candidates select the same customers in the same order. Give each experiment fresh input state, especially when one candidate mutates a set. Then measure the complete operation, including whatever materialization the caller actually needs.
Keep the input sizes, match distribution, culture, runtime and hardware consistent within a comparison. Short-circuiting makes the distribution of matches relevant. A tiny fixture is useful for understanding the code, but a large nonmatching population can emphasize very different costs. Record allocations alongside elapsed time, and inspect the generated code when a result contradicts your expectation.
There is value in doing this yourself. You can understand an explanation without having the experience of making a prediction, measuring it and discovering that you were wrong. That experience changes how you read the next piece of code. The quality of that experience matters far more to me than the letters after somebody’s name.
For a performance-critical path or a library built around such paths, my default is a simple loop. If it makes a larger method harder to follow, extract the selection into a clearly named method. The caller then sees one meaningful operation while the implementation remains straightforward to inspect.
Elsewhere, use LINQ and keep it simple. Its concise expressions are useful. Just remember that choosing the syntax is the beginning of understanding its cost.