Writing
Verified, Not Trusted: Designing Evals for AI Applications
Evals measure AI application behavior at the system boundary using deterministic graders and explicit rubrics. Results identify the model, effort and pass rates.
Topic
Evidence and reproducible checks for AI-generated claims, with explicit limits on what has been established and what remains uncertain.
5 pages
Writing
Evals measure AI application behavior at the system boundary using deterministic graders and explicit rubrics. Results identify the model, effort and pass rates.
Writing
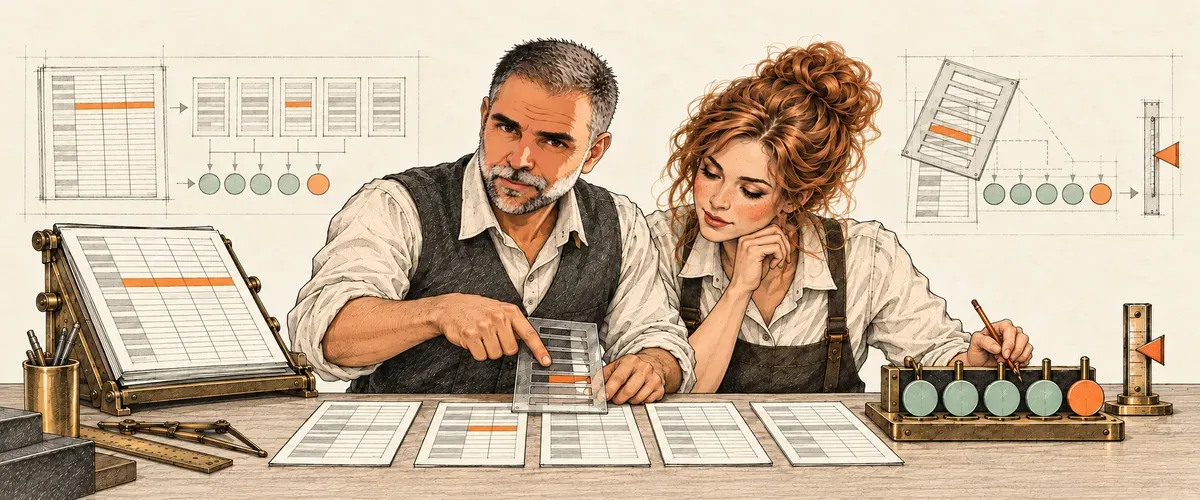
Evals measure reliability with reference keys, code graders, model judges and pass-rate gates. Expense examples show what to check and how structured output expands coverage.
Writing
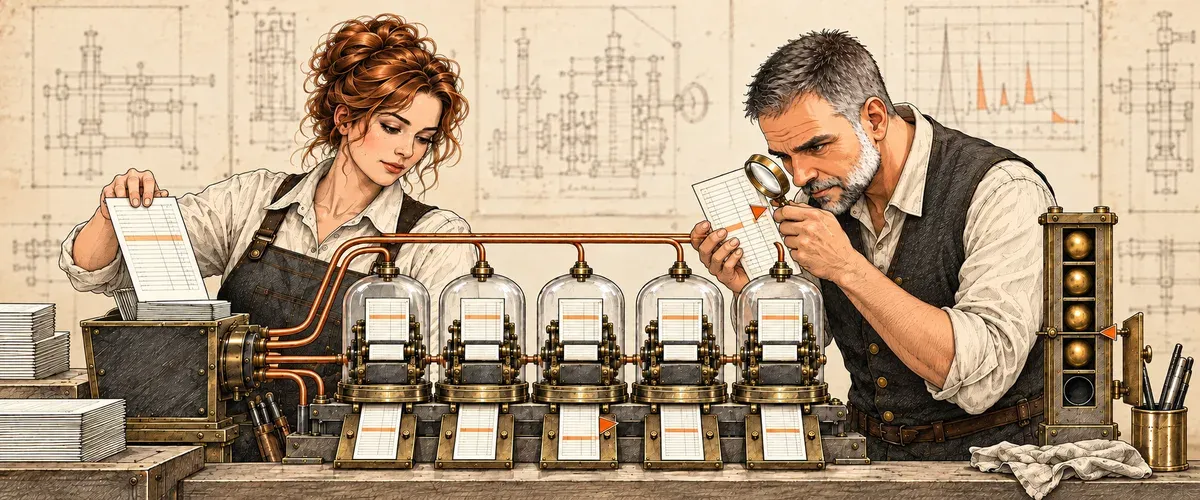
Evals are acceptance tests for prompts and skills: repeated isolated runs, a pass rate for each check, and a minimum pass rate as the gate. Code grades extracted facts and traces failures.
Writing
Imperative Python controls expense analysis and verifies model contributions through source evidence, reconciliation, and exact calculations. Models handle bounded judgments.
Writing
Expense totals need verifiable source coverage and reproducible calculations. Two prompts show how parsing, category rules, refunds, and code shape the evidence.