For decades, software delivery held a balance nobody designed.
Developers produced code at the pace of human cognition, carrying the requirement, the existing system, the design, the edge cases and the consequences in their heads, revising earlier decisions as understanding changed. Every change went through code review, and those reviews landed where they have always landed, on the leads and senior engineers. Who else would an organisation trust with them?
Verification sat downstream. A QA function ran its cycle toward the end of every release, alongside the unit suites every company runs, since no company on earth has ever publicly claimed not to test.
So many features shipped per quarter. Defects came back at a rate everyone had learned to live with. The cadence held, because every stage downstream of writing code was calibrated to one speed.
Keep that word. Calibrated. This whole story is what happens when one part of the system stops honouring the calibration, and what was hiding underneath it the entire time.
Because that equilibrium was never evidence the system worked. The defects returning from production were evidence it did not. They simply arrived slowly enough to be accepted as normal, a cost of doing business. The old SDLC was already flawed. Human coding speed kept the volume within reach of the people compensating for it.
The warning light was already flashing
Before AI enters the picture at all, look at what the industry was living with.
The unit suites ran green on every build. Isolated, mock-heavy, each component tested on a bench. And QA kept finding backend defects those suites had missed. Production found more still. Both facts were true for years, and almost nobody treated it as a contradiction.
The testing pyramid never answered that contradiction. If the unit tests are passing and QA is still finding backend defects, what exactly did those tests establish about the system we were about to ship? The industry kept running its suites and paying for the human backstop. We accepted the defects without accepting what they said about our tests.
Unit testing has never given us the confidence that the whole system meets its requirements and is ready for production. QA doing that verification afterward is the gap made visible. AI generation now feeds that same gap at a speed the human backstop cannot absorb.
It is worth being precise about what a green suite proves in that setup. Mocks replace evidence with assumptions. An isolated test proves that a simulation agreed with itself, which is a different claim from the assembled system behaving correctly. A component can pass every isolated test and still be absent from the running system: registered incorrectly, disabled by configuration, never called at all. Testing an engine on a bench does not prove the engine is connected to the wheels.
Which leaves one explanation for why QA was manually verifying backend behaviour: the automated verification beneath it had never proved the system as a whole. QA was the human backstop for that gap, and its workload was the measure of how much the tests were missing. Without that human layer, more would have escaped.
So the recurring defect stream was not an unavoidable property of software. It was evidence that the verification model was insufficient, and the industry learned to live with it.
A Porsche engine in a jalopy
Then organisations installed AI coding assistants. They dropped a Porsche engine into the old frame and expected to break speed records.
Developers accepted generated code a block at a time, then a feature at a time. Generation speed climbed away from human cognition speed. The adoption dashboards looked wonderful.
Faster generation alone does not establish faster reviewed and verified delivery. The reason sits exactly where code goes after it is written. Faster generation does not make the downstream work disappear. It makes that work arrive faster at two fixed checkpoints, code review and verification, both staffed by humans whose capacity is bounded by headcount.
The moment anyone pressed the accelerator, the existing weaknesses amplified. The wheels came off. The chassis buckled under machine-speed torque. Testing that was already porous became visibly porous once code started arriving at machine speed.
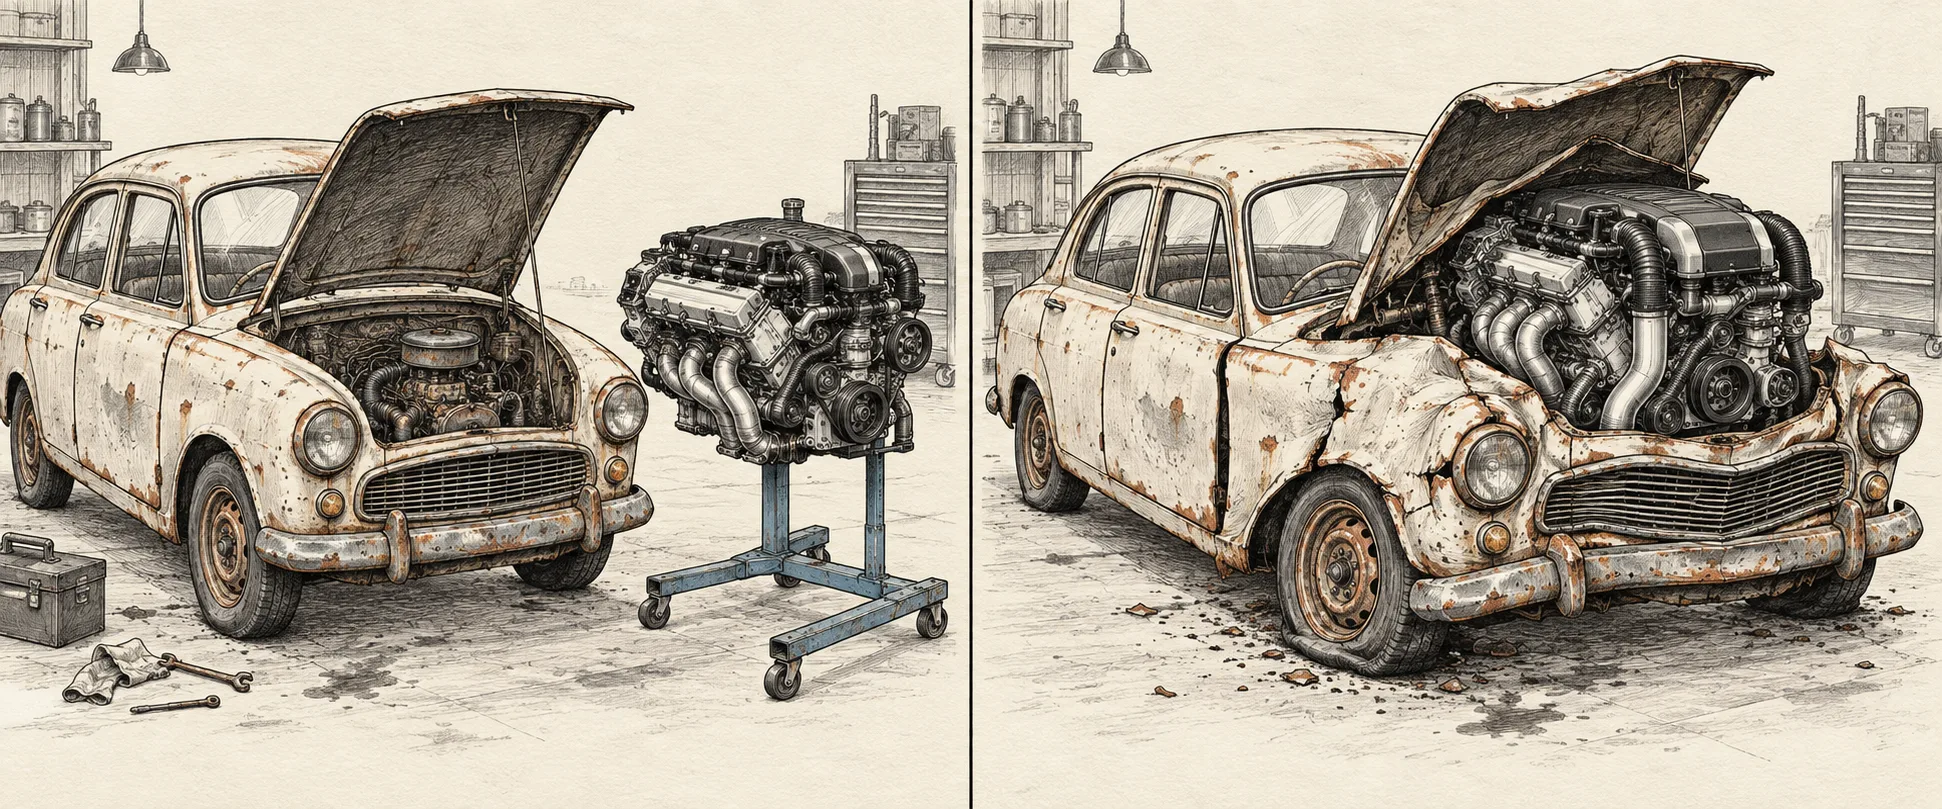
AI did not create the weakness. It made the weakness impossible to ignore. The engine was never the problem, and the fix is not another engine.
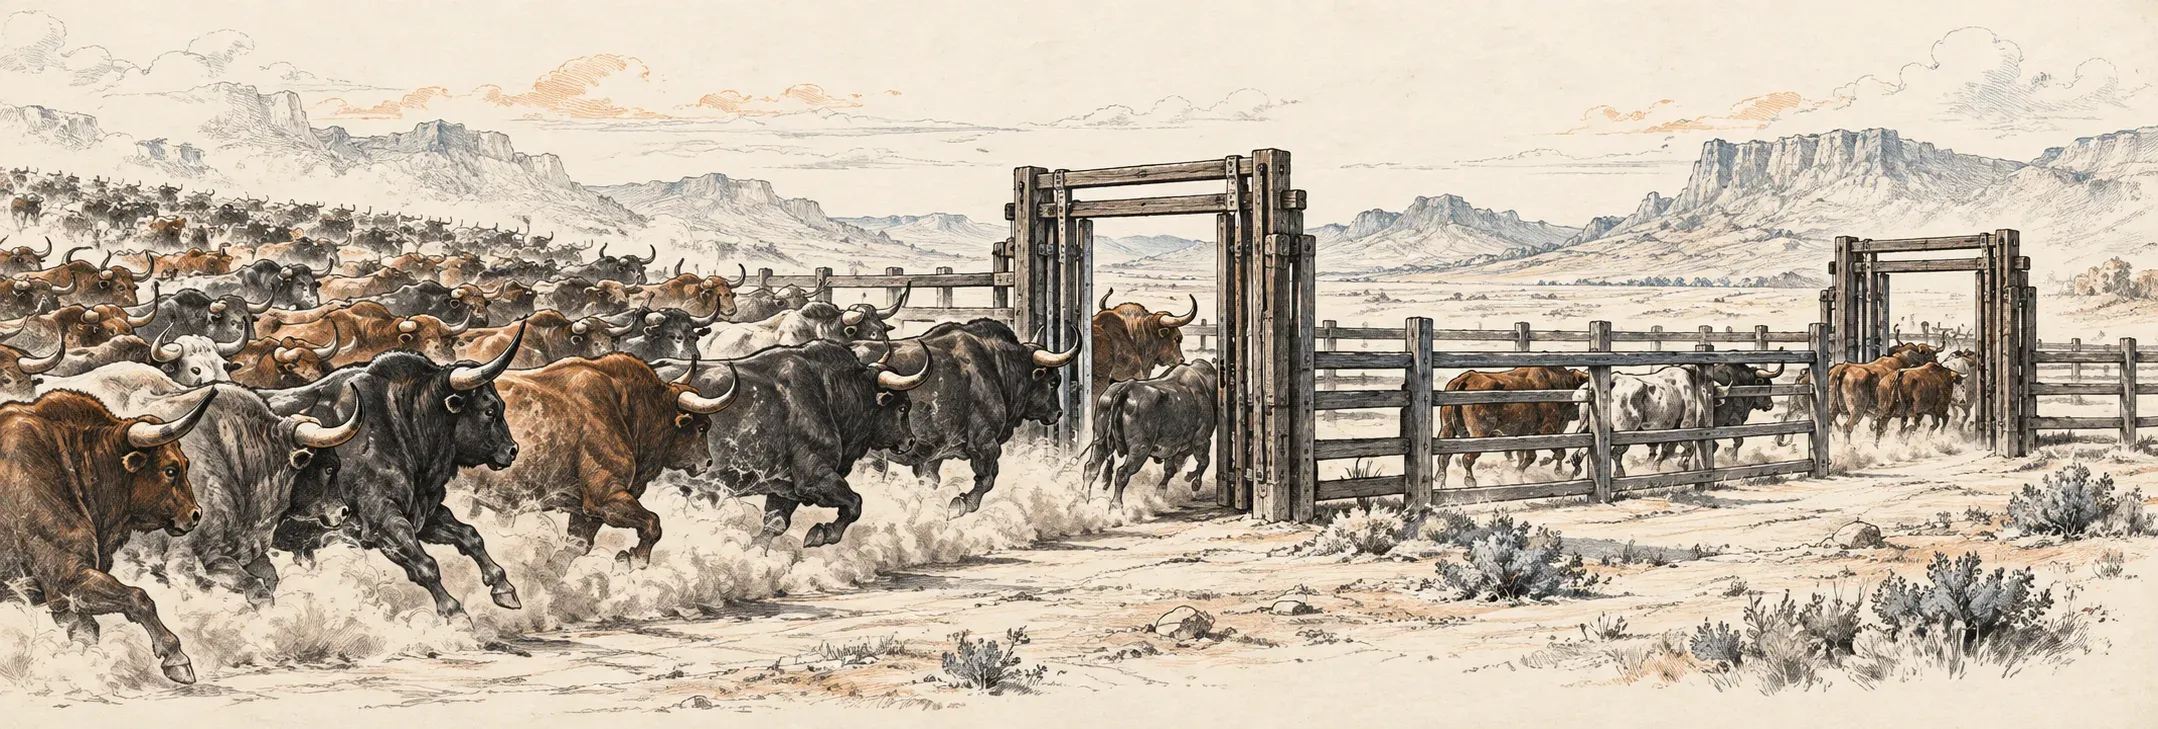
Stampede at the gates
Code is now written at machine speed. It is still reviewed and verified at human cognition speed. Between written and shipped sit two gates in series, each with fixed throughput. Gate one is code review, human judgement on every change. Gate two is verification, proof that the system still works.
The bottleneck has moved, from writing code to trusting it.
The name borrows from the thundering herd problem in systems engineering, where many processes wake at once and contend for a single scarce resource. The mapping is exact rather than decorative. Many generated changesets arrive together and contend for scarce reviewer attention, then for scarce verification capacity.
One difference makes this version worse than the classic. A thundering herd wakes on an event and then disperses. This herd is continuously generated. It never stops arriving.
A caution on the metaphor before going further. The stampede describes volume dynamics. The herd is the changesets, never the engineers producing them.
The numbers are already in
This is not a prediction. The studies below report pressure on review, verification and production reliability.
Code output roughly doubles. An enterprise that mandated AI assistance saw pull request throughput reach 2.09 times its baseline, with reviewer load doubling alongside it. The study’s own title says it: “AI Writes Faster Than Humans Can Review”. (CMU and Stanford, 2026, 802 developers and 196,000 pull requests.)
Human oversight is already scarce. Among 33,596 agent-authored pull requests sampled from popular repositories, 61% had no recorded review. Of the reviewed pull requests in that same population, only 10.14% received human-only review. That is thin recorded human oversight of the arriving volume. (Duma and others, 2026, in-the-wild data.)
Waving it through has a price. Telemetry across 22,000 developers shows bugs per developer up 54%, production incidents per pull request up 242.7%, and median review time up 441%. (Faros AI, 2026, 4,000 or more teams.)
Deployments break more often. Every 25% increase in AI adoption correlates with a 7.2% drop in delivery stability, meaning how often changes break production and how long recovery takes. That association has been negative for two annual reports running. (DORA, 2024 to 2025, around 5,000 respondents.)
Tests multiply, verification does not. 81% of enterprise leaders report more production issues, and 70% say maintaining the test suite now outweighs writing the code itself. AI multiplies tests too, but tests coupled to the implementation break with every change. Volume went up. Verification realism did not. (CloudBees, 2026, 200 or more enterprise technology leaders.)
Different studies, different methods, different commercial incentives, downstream pressure. DORA’s own phrase for the mechanism is that AI amplifies what is already there, including your weaknesses.
Why widening gate one fails
The intuitive response is to relieve the first gate. Add reviewers, loosen the bar, accept more on trust, point a generic AI reviewer at the queue.
Every one of those increases the flow rate through gate one. None of them reduces the herd.
Two of them fail on their own terms before we even get to the relocation problem. Waving work through abandons the review gate’s purpose. In Duma’s sample, 61% of agent-authored pull requests had no recorded review to examine. Pointing a generic AI reviewer at the problem runs into SWE-PRBench: its eight evaluated models detected between 15% and 31% of human-flagged issues in the diff-only configuration.
But suppose you did relieve gate one. You have not removed the queue. You have relocated it to gate two, the last checkpoint before production, where a miss costs the most and is caught the latest.
Before: the review queue
After: the verification queue
This is textbook Theory of Constraints. Speed up a non-constraint and system throughput does not move. All you have done is accumulate inventory in front of the real constraint, and in software that inventory is unverified code sitting in a holding pen.
The traffic analogy works too. What causes a motorway pile-up is speed differential between adjacent lanes rather than speed by itself, and generation now moves at a radically different speed from everything downstream of it.
Who is checking whom
Gate two is where the herd actually lands, and here the instinct is always the same: testing, we already do that.
So start with a question instead. If the AI writes the code, and the AI writes the tests, who is checking whom?
Tests that mirror the implementation inherit its assumptions. They mock its internals, and when the assistant regenerates the code it can regenerate the tests to agree with it. Calling that an eval changes nothing about what has been checked. Are Coding Agents Generating Over-Mocked Tests? found greater use of mocks in the studied agent-authored test commits. VibeCheck found weak assertions in generated suites across 15 student-developed repositories. Generating more tests with those weaknesses does not establish that the feature meets its requirements.
Gate two runs the full regression suite of functional acceptance tests at the boundary. Each feature adds its scenarios to that suite. Every subsequent change runs against the accumulated behaviour the system must continue to satisfy.
Functional acceptance testing at the boundary exercises the entire running system. Nothing inside it is mocked or altered to make it testable. Carefully arranged data and conditions establish the scenario, and the action enters through the system’s real boundary. Assertions then inspect the actual outcomes at its true edges.
The order-confirmation email really sends and really lands in a real inbox. We assert the recipient, the order number in the subject, and the line items and total in the body. The database write is checked column by column. A message to the broker is picked up by a real subscriber on the far end and its attributes asserted. Each assertion has an expected value derived from the requirement. A check that something ran without error cannot establish these outcomes.
Verify the tests against the specification. Establish that the functional acceptance tests at the boundary demonstrate every required scenario for the feature. Then run the full accumulated regression suite.
The care in the arrangements and the depth of the assertions determine what a passing test means. AI can help author these tests, but it must follow specific guidelines for functional acceptance testing at the boundary. A human reviews and ratifies the scenarios, arrangements, and assertions before they become the standard the implementation must meet. The implementation assistant cannot change that standard to make its code pass.
Verified, not trusted. That applies to the tests themselves. Verification compares the feature specification with the functional acceptance tests at the boundary and checks whether those tests actually demonstrate every required scenario. Every business requirement, acceptance criterion, and relevant technical and non-functional obligation must have appropriate verification. A requirement mentioned in a test name or comment is not enough. The arrangement must exercise it and the assertions must establish its outcome. Where an obligation needs another method, such as a load test, that evidence belongs in the release decision too.
This verification requires a controlled workflow with explicit stages, evidence, and checks for incomplete work. A directed graph defines the permitted progression through those stages. Models can examine the evidence within that workflow; maintained executable controls enforce its required steps and retain the results. A skill can supply the guidance, but a prompt telling a model to verify everything cannot establish that every required check occurred. Model judgments still need scrutiny.
Only after the tests have been verified against the specification does a passing suite provide the evidence we intended it to provide. A green run of an incomplete suite leaves the missing scenarios unverified.
Because functional acceptance tests at the boundary judge observable behaviour, they can survive an implementation rewrite while the required behaviour remains the same. The tests become the durable asset. The code becomes regenerable output.
QA can then concentrate on UI and UX, where human judgment decides whether an experience is correct and how it should improve. During each sprint, QA evaluates the new features and uses AI assistance to automate repeatable UI checks. Those checks join the UI regression suite, so previous features do not require another complete manual pass every sprint. Human experience judgments remain human work. Backend behaviour is already covered by the regression suite of functional acceptance tests at the boundary.
AI-native SDLC explains how the review gate, test ratification, and verification gate fit together. The Verification with Intent section collects the guidance on testing strategy, arrangements, and assertions.
Engineer the gates, do not widen them
I reached this position long before AI code generation. I wrote unit tests, questioned what they were establishing, and stopped using them. I moved to functional acceptance testing at the boundary around 2008 to 2010. I did not need a QA team manually verifying my backend services. QA focused on UI and UX.
Writing functional acceptance tests at the boundary took as much time as writing the production code, sometimes more. The arrangements had to be exact and the assertions had to establish the outcomes. That work gave me the confidence to go to production.
I care deeply about maintainable code. Programming With Intent is built around it. But if I had to choose where to spend my time, I would choose functional acceptance testing at the boundary. Maintainability matters throughout the life of the code. These tests give me the evidence I need to decide whether to ship it.
You do not relieve a stampede by opening the gates wider. Widening a gate means lowering its standard, and a gate with no standard is a hole in the fence.
Engineer both gates as one system, so the pipeline moves as fast as the code being written without quietly losing what review and verification were there to catch.
Verified, not trusted. Verify that the functional acceptance tests at the boundary demonstrate every required scenario for the feature. Ratify their arrangements and deep assertions against the requirements. Run the full accumulated regression suite against the actual system. Passing that suite is the evidence I rely on for the backend release decision. Unit tests and an assistant approving its own work have never given me that confidence.
Anyone selling a fix for gate one alone is selling a stampede relocation service.